Paper Scout
Project · agent skill · 2026
Paper Scout is a free, open-source agent skill that turns a research question into a ranked, de-duplicated reading list of real papers, a BibTeX file and an interactive citation map. It is the first step of the Research Suite, followed by Claim Conflict Finder and Research Dossier.
What it does
An agent that supports the SKILL.md standard (Claude Code, Codex CLI, Cursor, Gemini CLI) reads the skill's instructions and drives a single Python script, scripts/scout.py, through a fixed sequence:
- Search OpenAlex, Semantic Scholar and arXiv with three to six search strings written from different angles. All three APIs are free and need no key.
- Snowball through the references and citing papers of the best hits.
- De-duplicate across sources by DOI, arXiv id and normalised title, keeping the richest metadata and flagging preprints.
- Rank every paper, then let the agent screen titles and abstracts the way a researcher would.
- Write
references.bibandcitation_map.html.
Ranking
The score combines three parts:
- Relevance (55%)
- overlap between the question's terms and the paper's title (counted twice) and abstract.
- Impact (30%)
- citations per year since publication, plus how often the paper is cited by others in the same set.
- Recency (15%)
- where the publication year falls within the set's range.
Papers without an abstract are marked down by 10%.
No invented papers
The skill's first rule is that every paper must come from an API record with a DOI, arXiv id or URL. If the APIs can't be reached, it says so instead of filling the gap from memory. Preprints are always labelled as not peer-reviewed, and the final report lists which sources answered and which failed.
The citation map
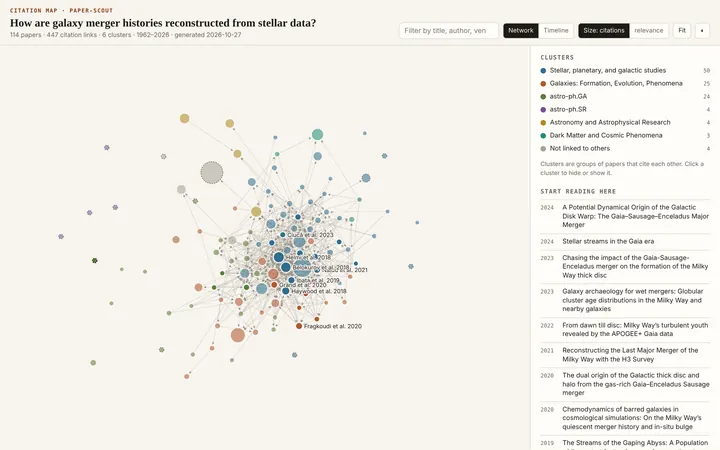
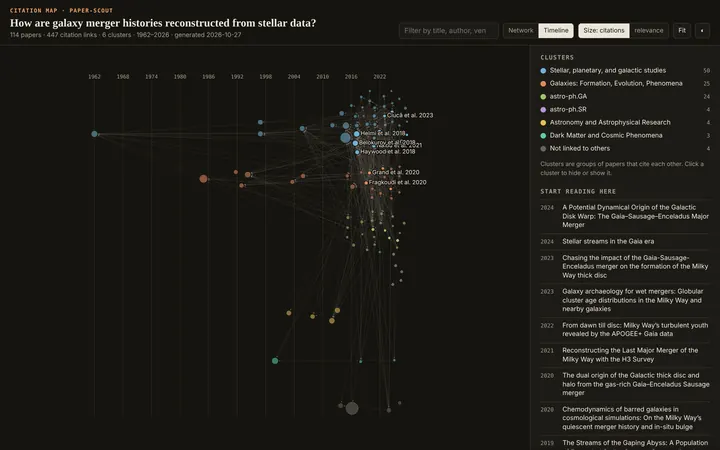
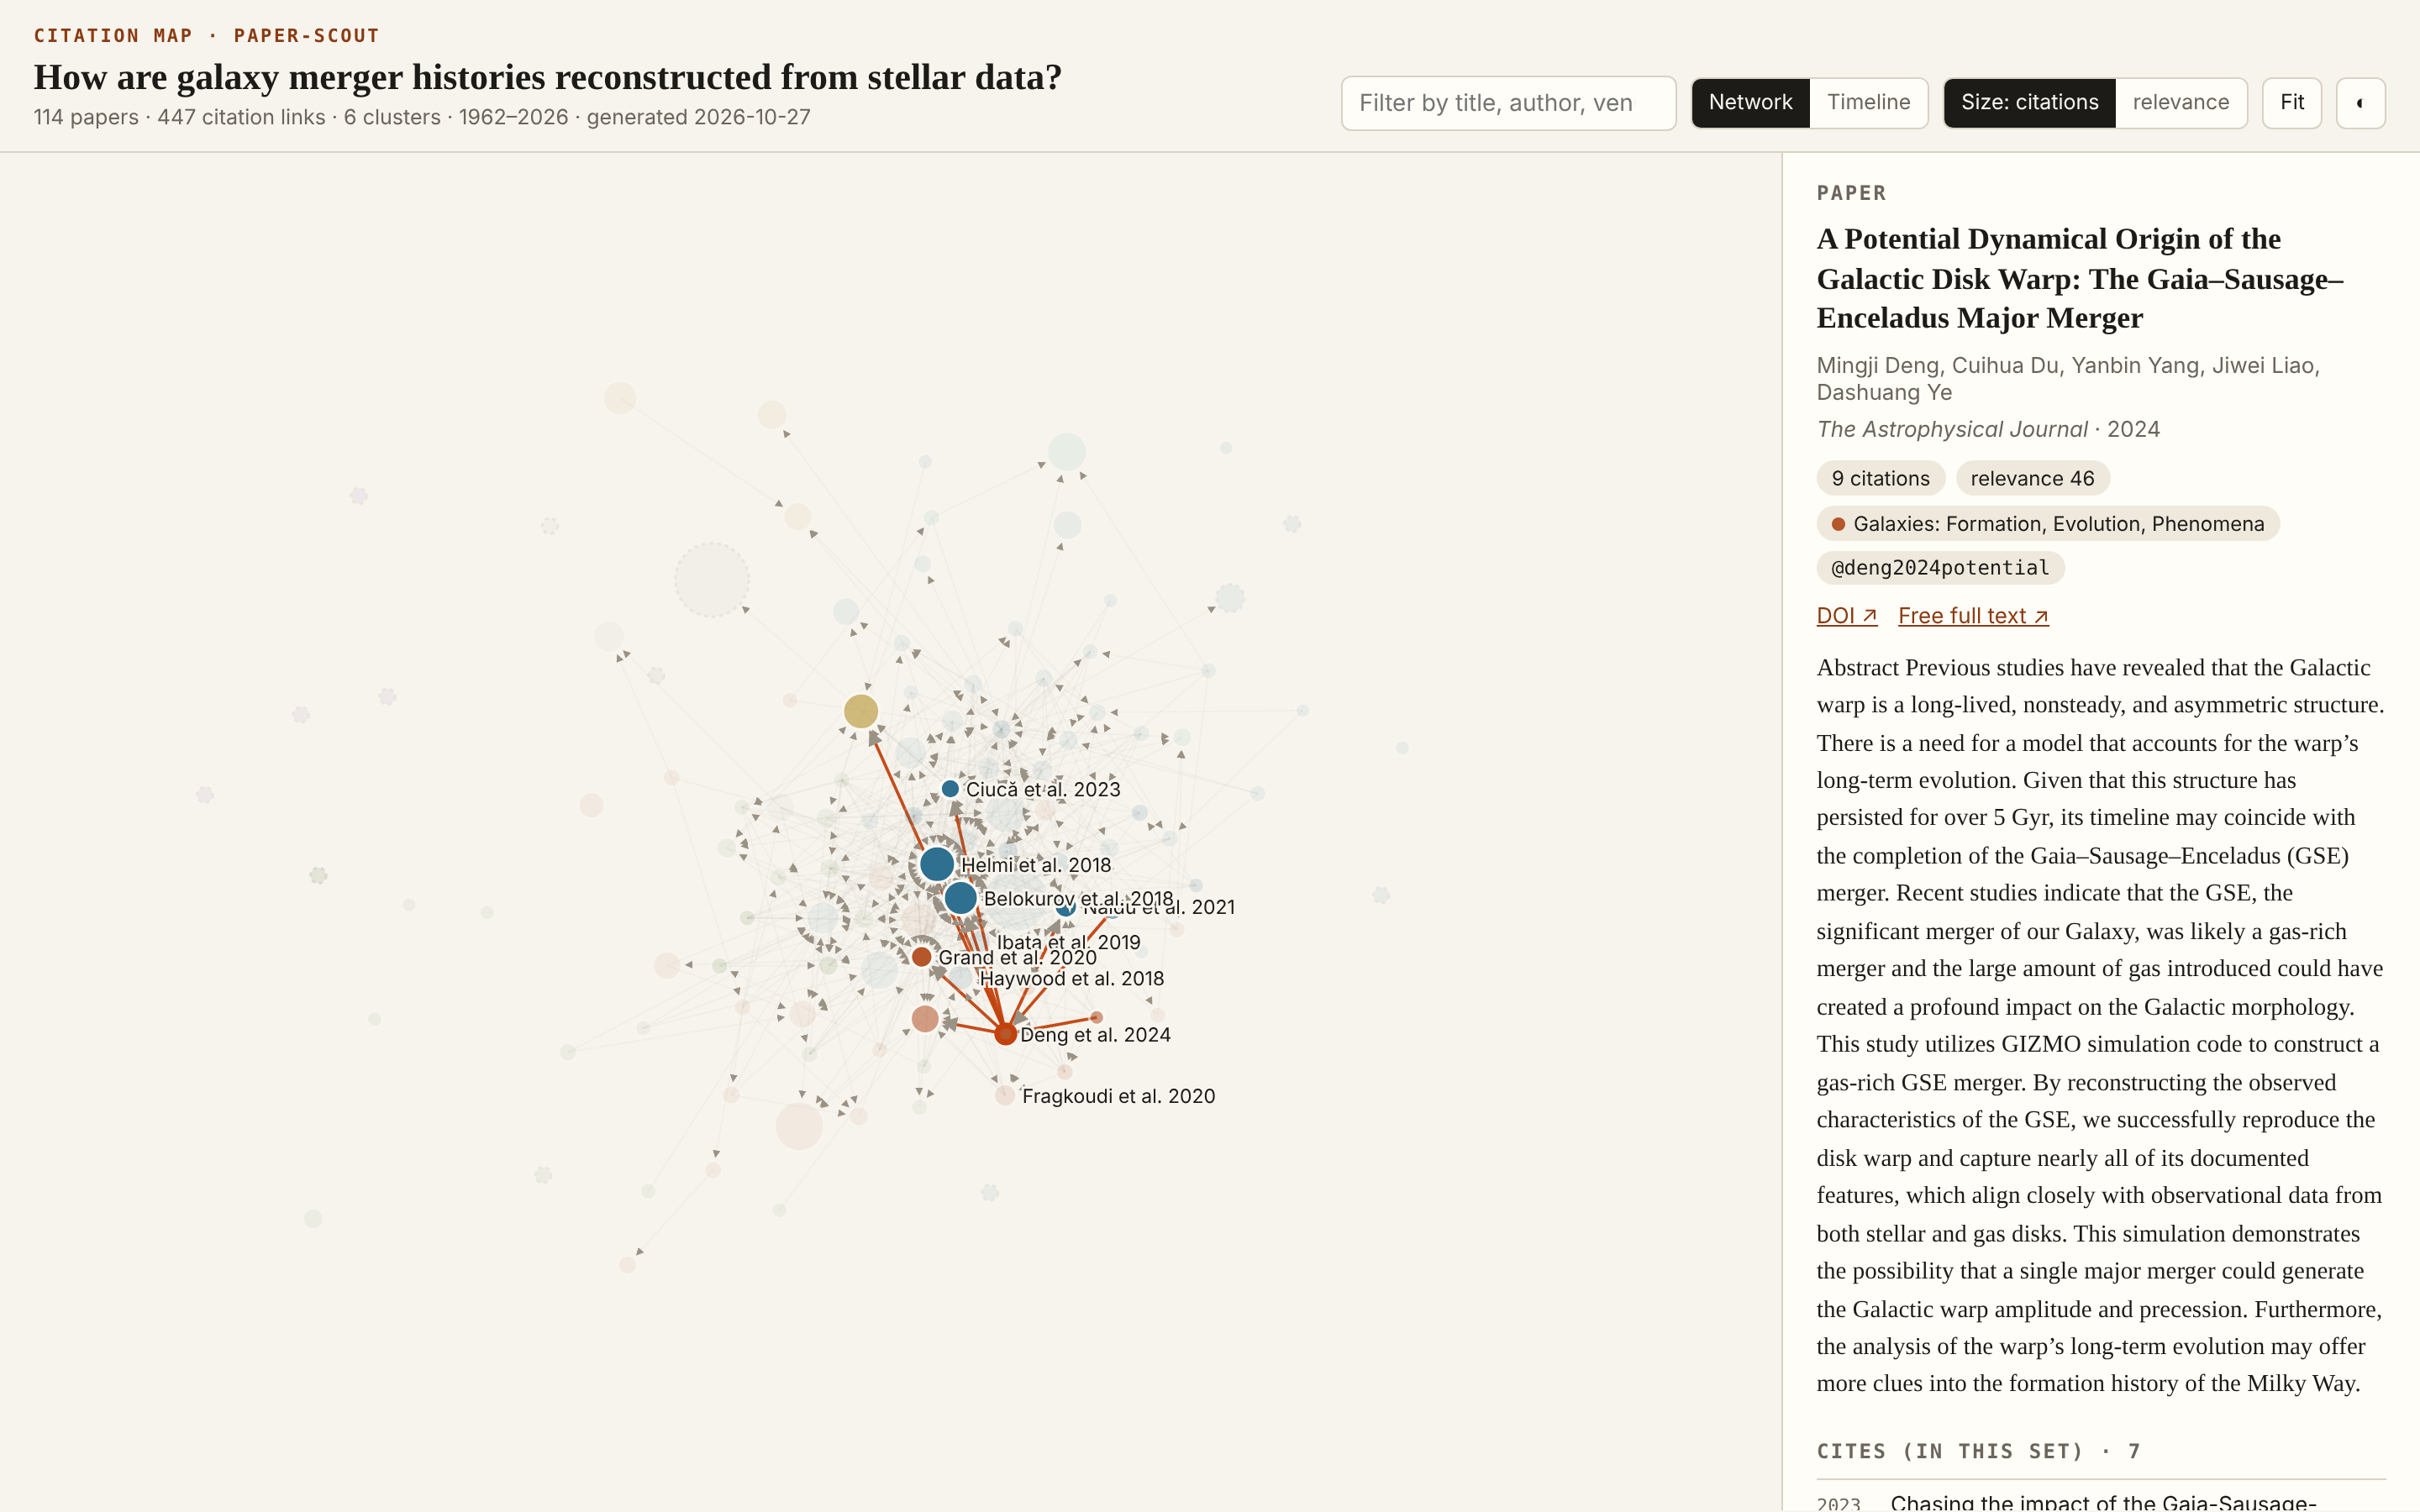
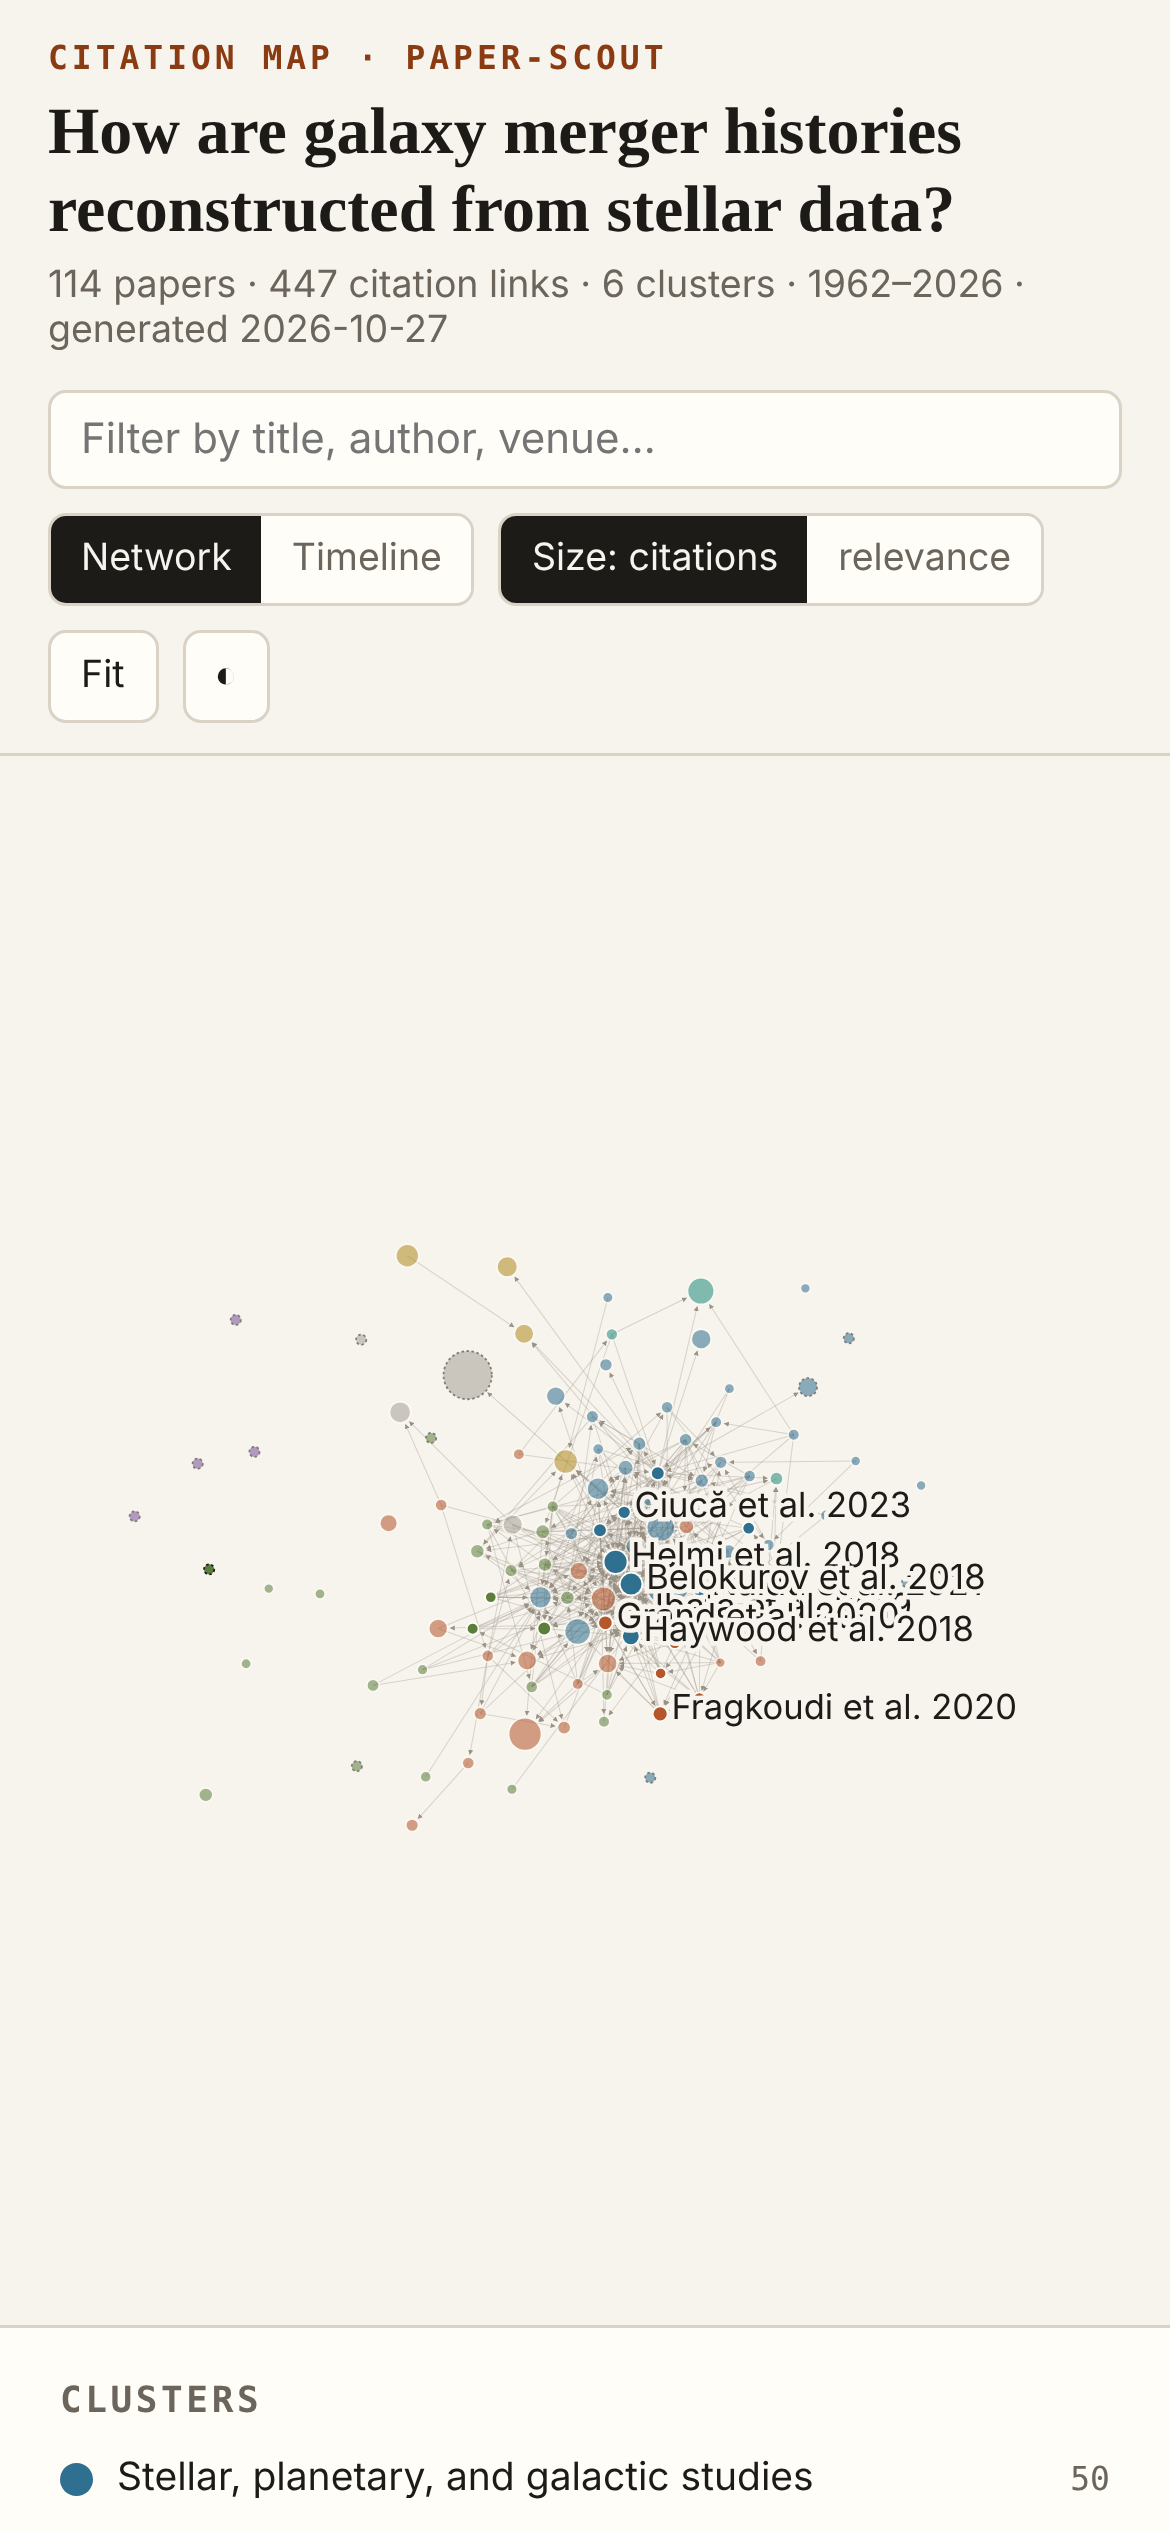
citation_map.html is a single offline page with two views: a network of research clusters showing who cites whom, and a timeline of how the ideas developed. Clicking a paper opens its abstract, links and in-set citations. The page makes no network requests.
The repository includes a real run on "How are galaxy merger histories reconstructed from stellar data?": 114 papers from OpenAlex and arXiv, connected to his galactic merger work at NARIT.
Running it
python3 scripts/scout.py search --out research/topic --query "…" --terms "…" "…"
python3 scripts/scout.py rank     --out research/topic --keep 40
python3 scripts/scout.py snowball --out research/topic --top 5
python3 scripts/scout.py bib      --out research/topic
python3 scripts/scout.py map      --out research/topic
The script needs only Python 3.10 or later. Offline unit tests run without network access, and tools/package.py builds a single-file zip for the Agensi marketplace.
See also
Pictures
In the knowledge graph
Paper Scout and the 15 things it is linked to. Open any dot for its page, or explore it in the full graph.
As data
Everything on this page is read from triples in the knowledge graph. These are the 28 it states about Paper Scout, and 7 more its ontology implies; the console runs SPARQL over the whole graph, here in your browser.
@prefix id: <https://ask.chaipat.cc/id/> .
@prefix rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#> .
@prefix cj: <https://ask.chaipat.cc/ns#> .
@prefix rdfs: <http://www.w3.org/2000/01/rdf-schema#> .
@prefix xsd: <http://www.w3.org/2001/XMLSchema#> .

id:PaperScout
    a cj:Project ;
    rdfs:label "Paper Scout" ;
    cj:description "Agent skill that finds real, citable research papers for a question, ranked, de-duplicated and mapped." ;
    cj:context id:OpenSource ;
    cj:repository "https://github.com/AppleBoiy/paper-scout"^^xsd:anyURI ;
    cj:firstCommit "2026-10-27"^^xsd:date ;
    cj:lastCommit "2026-10-27"^^xsd:date ;
    cj:commitCount 6 ;
    cj:kind "agent skill" ;
    cj:license "MIT" ;
    cj:theme id:ThemeAgentSkills , id:ThemeResearchTools ;
    cj:uses id:Python , id:AgentSkillsStd ;
    cj:tier 2 ;
    cj:implements id:Snowballing ;
    cj:integrates id:OpenAlex ,
                  id:SemanticScholar ,
                  id:arXiv ,
                  id:Agensi ;
    cj:handles id:BibTeXFormat ;
    cj:partOf id:ResearchSuite ;
    cj:mentions id:ClaimConflictFinder , id:MergerClustering , id:ResearchDossier ;
    cj:article "https://ask.chaipat.cc/wiki/PaperScout"^^xsd:anyURI ;
    cj:activeIn id:Y2026 ;
    cj:activity _:b122 .